优德官网 in the AIR

概述
日期
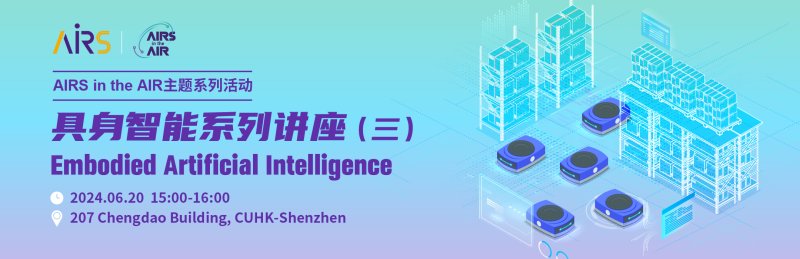
2024年06月20日
15:00 - 16:00
所在
香港中文大学(深圳)诚道楼207

优德官网 in the AIR | 具身智能系列讲座(三)

首页- 优德官网集团(中国)有限公司

具身智能是一种全新的人工智能理念,,, ,,,,它区别于古板人工智能的看法,,, ,,,,主张智能的爆发不但依赖算法和算力,,, ,,,,还需要通过与现实天下的互动来实现。。 。。 。。具身智能研究跨越了机械人学、人工智能、认知科学及神经科学等多个学科,,, ,,,,旨在深化对智能实质的明确。。 。。 。。

优德官网 in the AIR推出具身智能系列讲座,,, ,,,,旨在搜集相关领域顶尖学者专家,,, ,,,,探讨具身智能带来的新机缘,,, ,,,,解决其面临的手艺与应用挑战,,, ,,,,并将智能机械人应用推向家庭、工业、医疗和探索等多个领域,,, ,,,,增进人机交互的自然化和使命执行的效率化。。 。。 。。

系列讲座第三期约请爱丁堡大学信息学院副教授、自主智能体研究组认真人Stefano V. Albrecht,,, ,,,,他将分享团队在深度强化学习与大语言模子领域的研究效果,,, ,,,,包括深度强化学习在自动驾驶与多机械人仓储场景的应用和大语言模子在家用机械人中的应用等,,, ,,,,并且提出他关于大语言模子智能体研究的视察与思索。。 。。 。。

优德官网 in the AIR为优德官网重磅推出的品牌系列运动,,, ,,,,与您一起探索人工智能与机械人领域的前沿手艺、工业应用、生长趋势。。 。。 。。2022年举行至今,,, ,,,,已约请百余位海内外嘉宾,,, ,,,,吸引了超40万人次加入。。 。。 。。

  • 首页- 优德官网集团(中国)有限公司
    林天麟
    优德官网智能机械人中心主任、香港中文大学(深圳)理工学院助理教授
    执行主席
  • 首页- 优德官网集团(中国)有限公司
    Stefano V. Albrecht
    爱丁堡大学信息学院副教授
    From Deep Reinforcement Learning to LLM-based Agents: Perspectives on Current Research

    Dr. Stefano V. Albrecht is Associate Professor in Artificial Intelligence in the School of Informatics, University of Edinburgh. He leads the Autonomous Agents Research Group which specialises in developing machine learning algorithms for autonomous systems control and decision making, with a particular focus on reinforcement learning and multi-agent interaction. In his roles as Royal Academy of Engineering and Royal Society Industrial Fellow, he actively develops industry applications in the areas of multi-robot warehouses with Dematic/KION, and autonomous driving with Five AI which completed one of the most extensive urban road trials of autonomous driving in London before being acquired by Bosch in 2022. Dr. Albrecht is affiliated with the Alan Turing Institute where he leads the Multi-Agent Systems theme. In 2022, he was nominated for the IJCAI Computers and Thought Award based on his research which introduced Stochastic Bayesian Games and optimal solution algorithms, which have since been applied in a range of domains. Previously, Dr. Albrecht was a postdoctoral fellow at the University of Texas at Austin working with Prof. Peter Stone. He obtained PhD and MSc degrees in Artificial Intelligence from the University of Edinburgh, and a BSc degree in Computer Science from Technical University of Darmstadt. He is co-author of the new MIT Press textbook "Multi-Agent Reinforcement Learning: Foundations and Modern Approaches" which is freely available at www.marl-book.com.
    Since the recent successes of large language models (LLMs), we are beginning to see a shift of attention from deep reinforcement learning to LLM-based agents. While deep RL policies are typically learned from scratch to maximise some defined return objective, LLM-agents use an existing LLM at their core and focus on clever prompt engineering and downstream specialisation of the LLM via supervised and reinforcement learning techniques. In this talk, I will first provide a broad overview of my group’s research in deep RL, which focuses among other topics on developing sample-efficient and robust RL algorithms for both single- and multi-agent control tasks, including industry applications in autonomous driving and multi-robot warehouses. I will then present our recent research into LLM-agents, where we propose an approach for household robotics that takes into account user preferences to achieve more robust and effective planning. I will conclude with some personal observations about the state of LLM-agent research: (a) many papers in this field follow essentially the same recipe by focussing on prompt engineering and downstream specialisation; (b) this recipe makes their scientific claims brittle as they depend crucially on the specific LMM engine, and (c) LLMs are not natively designed to maximise objectives for optimal control and decision making. Based on these observations, I believe some fruitful research avenues can be identified.