优德官网 in the AIR

概述
日期
2023年11月28日
16:00 - 17:00
所在
运动行、Bilibili

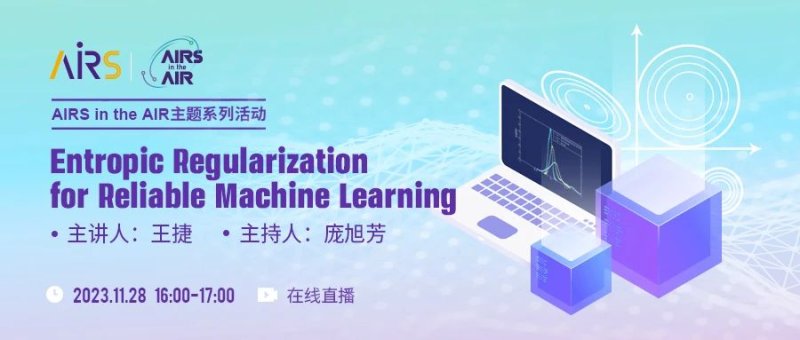
优德官网 in the AIR | 可靠机械学习的熵正则化

首页- 优德官网集团(中国)有限公司

第61期优德官网 in the AIR约请佐治亚理工学院工业工程系博士生王捷分享可靠机械学习与机械学习模子鲁棒性的相关研究。。。。。。。王捷曾在运筹与治理科学领域顶级期刊Operations Research揭晓论文,,,,,他现在在佐治亚理工学院工业工程系攻读博士,,,,,主要的研究偏向是不确定性下的决议,,,,,曾获2022 ISyE Robert Goodell Brown Research Excellence award、Winner in 2022 INFORMS Poster Competition等奖项。。。。。。。

通过Bilibili(http://live.bilibili.com/22587709)加入。。。。。。。

呼吸新鲜空气,,,,,相识前沿科技!优德官网 in the AIR 为 优德官网 重磅推出的系列运动,,,,,与您一起探索人工智能与机械人领域的前沿手艺、工业应用、生长趋势。。。。。。。

  • 首页- 优德官网集团(中国)有限公司
    庞旭芳
    优德官网特种机械人中心副研究员
    主持人
  • 首页- 优德官网集团(中国)有限公司
    王捷
    佐治亚理工学院工业工程系博士生
    Entropic Regularization for Reliable Machine Learning

    Jie Wang is a 4-th year Ph.D. student in Industrial Engineering at the H. Milton Stewart School of Industrial and Systems Engineering. He received BS degree in Pure of Mathematics Major from The Chinese University of Hong Kong, Shenzhen. His main research studies decision-making under uncertainty. His research has been published on several journals and conferences including Operations Research, Information and Inference a Journal of the IMA, NeurIPS, AISTATS, and ISIT. He has received several awards, such as 2022 ISyE Robert Goodell Brown Research Excellence award, Winner in 2022 INFORMS Poster Competition, and Winner for Best Theoretical Paper in 2023 INFORMS Workshop on DMDA.

    Despite the growing prevalence of artificial neural networks in real-world applications, their vulnerability to adversarial attacks remains to be a significant concern, which motivates us to investigate the robustness of machine learning models. While various heuristics aim to optimize the distributionally robust risk using the Wasserstein metric, such a notion of robustness frequently encounters computation intractability. To tackle the computational challenge, we develop a novel approach to adversarial training that integrates entropic regularization into the distributionally robust risk function. This regularization brings a notable improvement in computation compared with the original formulation. We develop stochastic gradient methods with near-optimal sample complexity to solve this problem efficiently. Moreover, we establish the regularization effects and demonstrate this formulation is asymptotic equivalence to a regularized empirical risk minimization (ERM) framework, by considering various scaling regimes of the entropic regularization $\eta$ and robustness level $\rho$. These regimes yield gradient norm regularization, variance regularization, or a smoothed gradient norm regularization that interpolates between these extremes. We numerically validate our proposed method in supervised learning and reinforcement learning applications and showcase its state-of-the-art performance against various adversarial attacks.

视频回首