概述
日期
2023年08月18日
09:00 - 10:00
所在
运动行、Bilibili

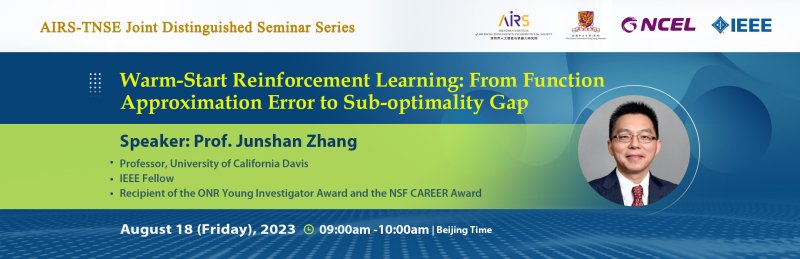
Warm-Start Reinforcement Learning: From Function Approximation Error to Sub-optimality Gap

首页- 优德官网集团(中国)有限公司

针对强化学习(Reinforcement Learning,,,,,, ,,RL)较高的采样重漂后和盘算负荷的问题,,,,,, ,,热启动强化学习(Warm-Start RL)正成为一种有前途的新范式。。。。。。热启动强化学习的基本头脑是通过离线训练初始战略来加速在线学习。。。。。。现在,,,,,, ,,热启动强化学习已乐成应用于AlphaZero和ChatGPT,,,,,, ,,这些应用展示了热启动战略在加速在线学习方面的重大潜力。。。。。。为了深入明确热启动强化学习,,,,,, ,,研究量化函数迫近误差对热启动强化学习次优差别的影响是至关主要的。。。。。。

第九期 IEEE TNSE 优异讲座系列运动,,,,,, ,,我们有幸约请到加州大学戴维斯分校的Junshan Zhang教授先容热启动强化学习,,,,,, ,,并分享他在这个领域内的相关研究效果与有趣发明。。。。。。

优德官网-TNSE Joint Distinguished Seminar Series is co-sponsored by IEEE Transactions on Network Science and Engineering (TNSE) and Shenzhen Institute of Artificial Intelligence and Robotics for Society (优德官网), with joint support from The Chinese University of Hong Kong, Shenzhen, Network Communication and Economics Laboratory (NCEL), and IEEE. This series aims to bring together top international experts and scholars in the field of network science and engineering to share cutting-edge scientific and technological achievements.

Join the seminar on August 18 through Bilibili (http://live.bilibili.com/22587709).

  • 首页- 优德官网集团(中国)有限公司
    Jianwei Huang
    Vice President, 优德官网; Presidential Chair Professor, CUHK-Shenzhen; Editor-in-Chief, IEEE TNSE; IEEE Fellow; AAIA Fellow
    Executive Chair
  • 首页- 优德官网集团(中国)有限公司
    Junshan Zhang
    加州大学戴维斯分校电子与盘算机工程系教授、IEEE Fellow
    Warm-Start Reinforcement Learning: From Function Approximation Error to Sub-optimality Gap

    Junshan Zhang,,,,,, ,,加州大学戴维斯分校电子与盘算机工程系教授,,,,,, ,,2000年于普渡大学获得博士学位,,,,,, ,,2000 年至 2021 年于亚利桑那州立大学任教。。。。。。他的研究偏向涉及信息网络和数据科学,,,,,, ,,包括边沿盘算人工智能、强化学习、一连学习、网络优化与控制、博弈论,,,,,, ,,以及这些手艺在互联和自动驾驶汽车、5G 及更高手艺、无线网络、物联网 (IoT) 和智能电网中的应用。。。。。。Junshan Zhang教授是 IEEE 会士,,,,,, ,,2005 年荣获 ONR 青年研究员奖,,,,,, ,,2003 年荣获 NSF 职业奖,,,,,, ,,2016 年荣获 IEEE 无线通讯手艺委员会认可奖。。。。。。他的论文曾获得多项奖项,,,,,, ,,包括WiOPT 2018最佳学生论文、ACM SIGMETRICS/IFIP Performance 2016 Kenneth C. Sevcik优异学生论文奖、IEEE INFOCOM 2009和IEEE INFOCOM 2014最佳论文亚军奖、IEEE ICC 2008和2017最佳论文奖。。。。。 ; ;;;;;;;谒难芯啃Ч,,,,,, ,,他于2015年配合建设了Smartiply公司,,,,,, ,,这是一家边沿盘算首创公司,,,,,, ,,为物联网应用提供增强的网络毗连和嵌入式人工智能。。。。。。

    Conventional reinforcement learning (RL) techniques face the formidable challenge of high sample complexity and intensive computation load, which hinders RL's applicability in real-world tasks. To tackle this challenge, Warm-Start RL is emerging as a promising new paradigm, with the basic idea being to accelerate online learning by starting with an initial policy trained offline. Indeed, owing to the knowledge transfer from an initial policy, Warm-Start RL has been successfully applied in AlphaZero and ChatGPT, demonstrating its great potential to speed up online learning. Despite these remarkable successes, a fundamental understanding of Warm-Start RL is lacking. The primary objective of this study is to quantify the impact of function approximation errors on the sub-optimality gap for Warm-Start RL. We consider the widely used ‘Actor-Critic’ method for RL. For the unbiased case, we give sufficient conditions on the question ‘how good the warm-start policy needs to be’ to achieve fast convergence. For the biased case, our findings reveal that a ‘good’ warm-start policy (obtained by offline training) may be insufficient, and bias reduction in online learning also plays an essential role to lower the suboptimality gap. We then investigate bias reduction using adaptive ensemble learning and planning.